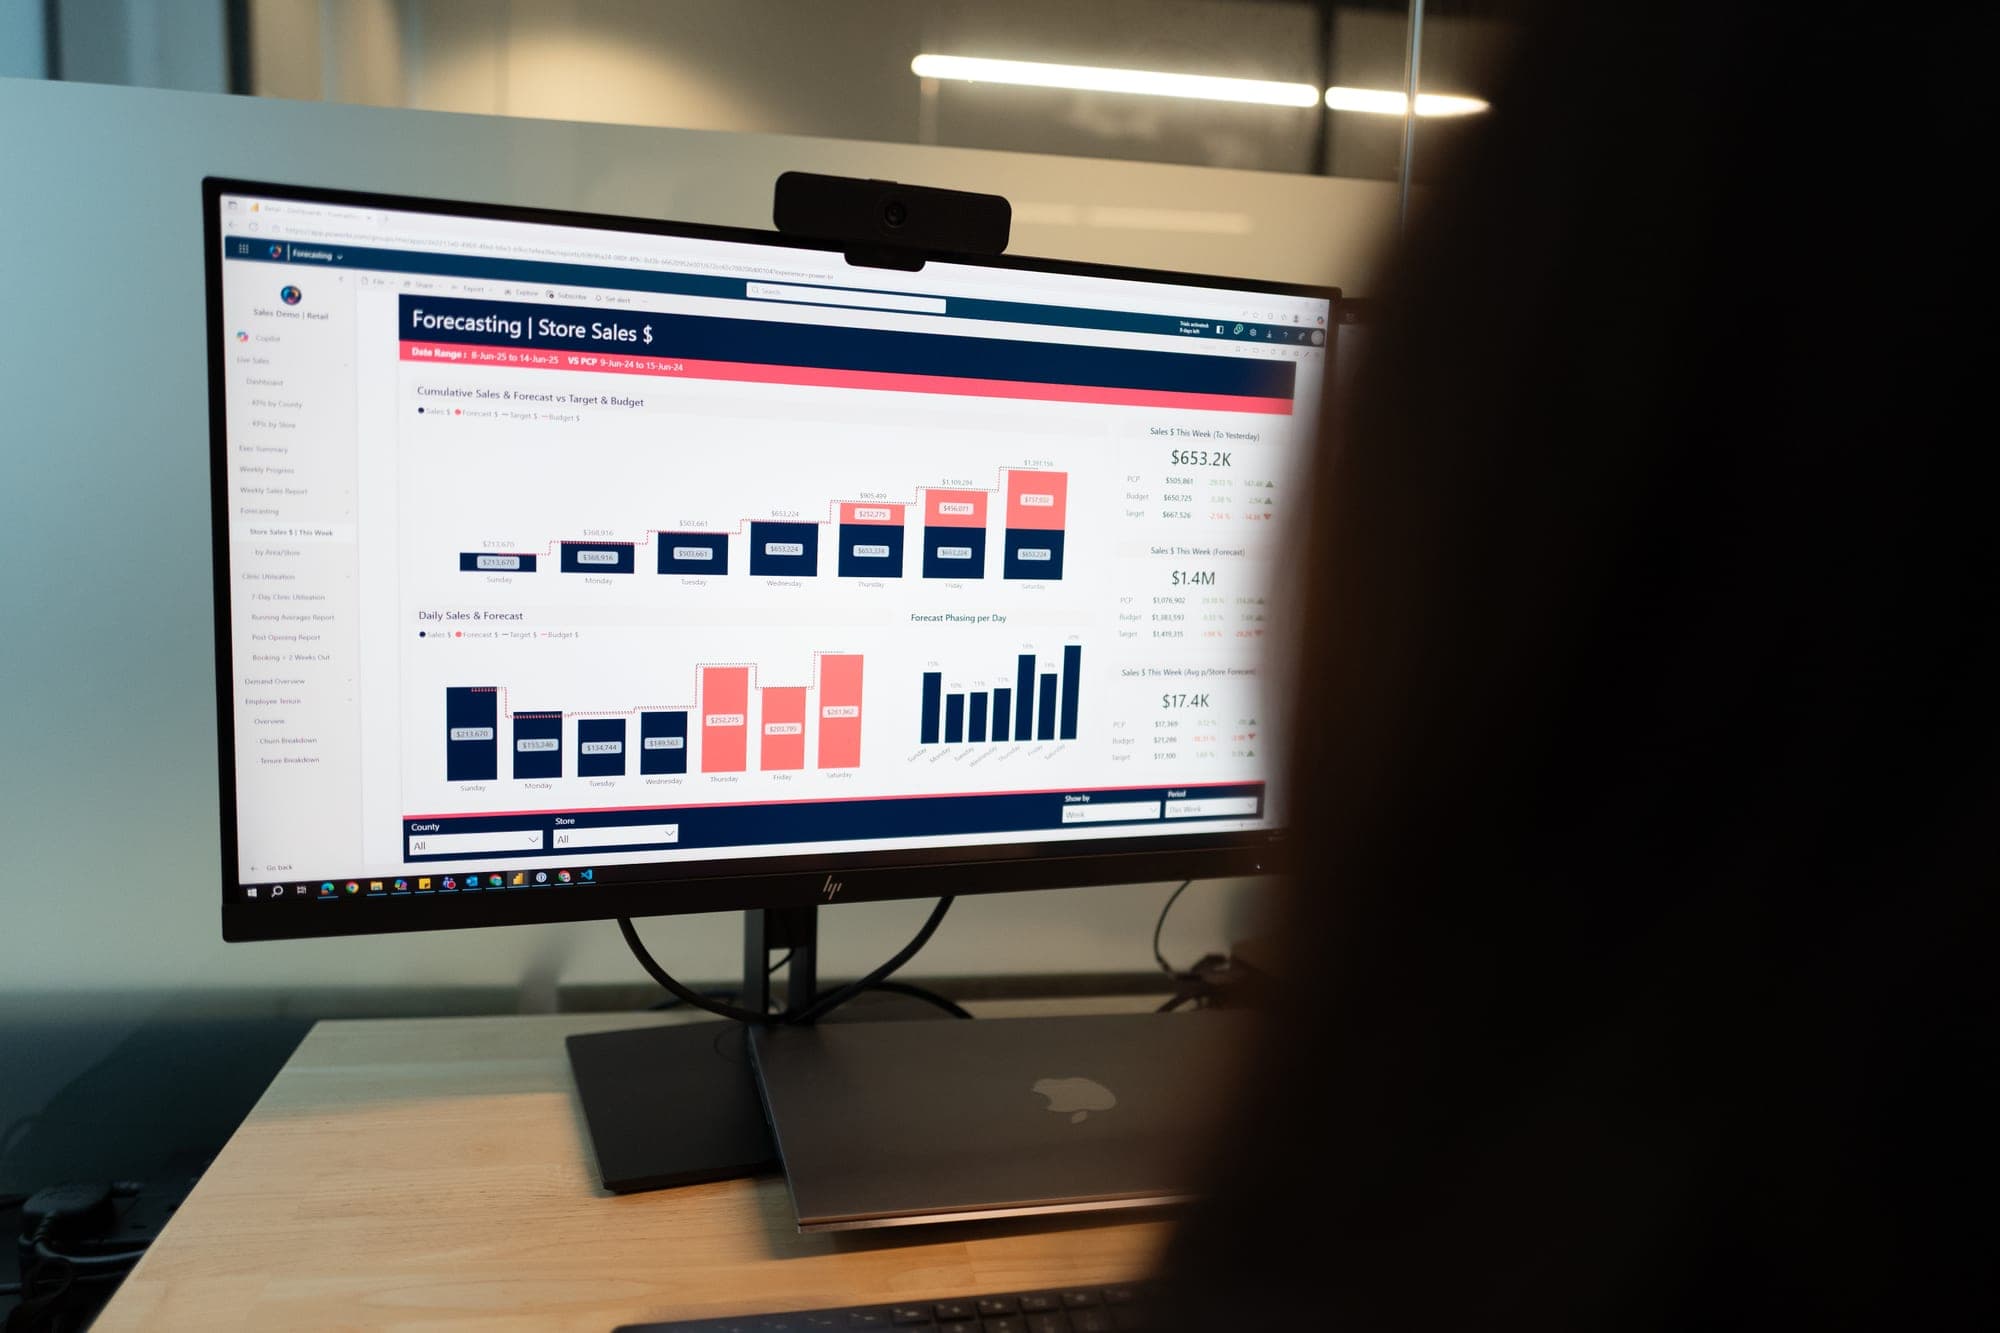
One began as a single simple flow, the other moves around 15,000 records a day across a hundred stores. Different contexts, different scales, and both built on the same integration accelerators. Here is what stays the same whatever the scale, and what changes.
Two integrations, one set of rules
We helped a design and engineering consultancy stop retyping won jobs into its delivery system. We also built and run an integration for a fast-growing retailer that keeps an ERP, a point of sale across two countries and an online shop in step, with around 18 pipelines and about 15,000 records moving every day.
The first began as a single automated flow, simple enough that an administrator could open it and follow each step for themselves. The second is a deployed service with an audit database, monitoring and alerts behind it. Different industries, different systems and very different scales.
Yet both were built on the same accelerators. The same connectors, sync patterns, transformation logic and monitoring sit underneath each of them, which is why the same principles apply whichever end of the scale you are at. Whether you are building one flow or an enterprise platform, the questions that decide whether an integration can be trusted do not change. You can read how each was built in the case studies on the consultancy and the retailer.
What the accelerators make possible
Because the foundations already exist, the plumbing is the quick part: connectors, sync patterns, transformation and monitoring that are already built and proven. That frees the time for the part that is specific to the client, and that is where the real work is.
It is rarely about moving data. The time goes on translating how a business actually works into clear, repeatable business logic, and then handling the edge cases.
We recently delivered two integration projects, each in around five days. Speed like that comes from not rebuilding the foundations each time. It does not mean the thinking is skipped.
We also do not pretend we can find every edge case on day one. Nobody can, because people work in ways that only show up when real records start flowing. So every integration goes through a running-in phase. We trace anomalies as they appear and react quickly, tweaking the flows until the exceptions are handled. That is a normal part of delivering an integration properly, and it is what the principles below are designed to support.
What changes with scale
Scale changes how much machinery you need, not what the integration has to get right.
- Tactical. One system watches for an event and does a job in one or two others. It might run in a platform such as Power Automate or Make, particularly if the client wants to extend it themselves. It needs to be understandable, correct and easy to switch off.
- Enterprise. Many systems, several regions, several currencies and thousands of records a day. It needs an audit trail, monitoring, alerting, automated tests and written documentation, because nobody can hold it all in their head.
The consultancy project shows the range in a single engagement. It grew in three phases, from one flow to a deployed, monitored service, and the team did not need a new platform at any point.
Code first, low-code when you want to build too
Our view is simple: nearly everything is easier in code. You have full control of the logic, how errors are handled and what gets logged, and the rules do not have to be squeezed into what a visual builder allows.
We still work with platforms like Power Automate and Make, and we choose them for a specific reason: the client wants to add capabilities themselves. In that case we build the complex flows in the platform, and the client’s team takes on the more straightforward ones. They get the freedom to extend it, and the hard parts are already done properly.
Recently we have delivered three smaller integrations, one on a low-code platform and two bespoke.
- Low-code: Make. A simpler integration with a professional services automation (PSA) platform.
- Bespoke: the consultancy project. The one described in the case study, written in code.
- Bespoke: a CRM to PSA sync. An integration that syncs HubSpot with a client’s PSA platform, also written in code.
The advantage of code shows most when the rules get complicated. Several regions and currencies, tax that has to reconcile to the cent, orders that ship in parts and are edited afterwards, stock moving between suppliers, warehouses and stores. At that point the logic is the hard part, and a visual builder or an off-the-shelf integration platform starts to fight you.
The retailer is a good example. An off-the-shelf integration application had struggled with the combination of complexity and volume. Code gave us control over every rule, and let us build the audit, retries and monitoring that make an integration trustworthy at that volume.
So the choice is less about which tool is better and more about who needs to own the flows afterwards.
Principles that hold at any scale
1. Document and align on the core business logic
This is always step one. Before any connector is configured or any flow is built, write down how the business actually works and get everyone to agree it: what counts as a sale, which system owns which fact, and what happens when two systems disagree.
Most of an integration’s real effort is translating working practices into clear, repeatable rules, and that translation is far cheaper on paper than in code.
2. Start with one flow, end to end
Prove one flow on real records before you agree what the rest will look like. It is a cheap way to find out what your systems actually do, as opposed to what their documentation says, and it usually changes the plan for everything that follows.
The retailer began with a proof of concept connecting a single system. The consultancy began with one flow, before agreeing what the rest would look like.
3. Know what already exists before you write anything
The obvious design, “give me the records that are not in the other system yet”, has a trap. The thing that prevents duplicates also makes every existing record invisible, so a change can never reach it.
Ask the question for each record instead. Find it first by a reference stamped on records you created, then fall back to business attributes such as a name, an email address or a project reference. If a record matches two things, stop and report it. Writing to the wrong record is silent, and nobody finds it later.
4. Write only what moved
Source systems mark a record as updated when any field changes, including the many nobody maps. Compare the record with what the destination holds, and write only the real differences.
Decide in advance who wins when the two disagree. In our experience, if the source is blank and the destination is not, the destination should win. Blanking a field somebody filled in by hand is worse than being briefly out of date.
5. Make every run safe to repeat
Every record that lands in the destination should carry a reference back to where it came from. Then running a flow again updates rather than duplicates, and an interrupted run is simply run again, not untangled by hand.
This is the principle that matters most as volumes rise. The retailer’s flows retry temporary errors automatically, and a second attempt does not create a second invoice.
6. Let problems repair themselves, and keep them small
One bad record should hold up only itself. The run carries on, and the record is set aside. Where the cause is temporary, retry. Where a record cannot be completed properly, such as a job with no client attached, hold it back and report it instead of creating something half-finished. Many systems will not let you delete a record once it exists, so a wrong one has to be repaired in place.
Where the next run can pick up a record that was set aside, once the cause is corrected, it goes through without anyone re-triggering anything. That is what we mean by an integration that repairs itself.
7. Make mistakes visible
At small scale, visibility can be as simple as a list of what crossed and what did not. At enterprise scale, it is an audit log that records every record and every run, a dashboard, and a daily report of anything that could not be processed.
What the report shows is rarely a technical fault. On the retail platform, the problems the audit catches are almost all cases of a source system being used incorrectly, such as a product code that does not exist in the other system or a store name that does not match. The integration reports exactly what is wrong, so the problem is fixed at the source and the next run picks it up.
An integration that exposes data quality problems is doing more than moving data. It is also what makes the running-in phase work: anomalies are traced from the audit log and fixed quickly, not discovered later by somebody in the business.
8. Decide what correct means, and prove it
A document in the destination should match what actually happened at the source. For the retailer, that meant reconciling to the cent against what the customer paid at the till. The ERP calculates its own tax, which is often a few cents out from the point of sale, and the payment is based on the tax-inclusive figure. So every document is checked after it is created, and a rounding line closes any gap.
At smaller scale, the same idea is simpler: agree what a correct record looks like, and check for it automatically.
9. Build it to be adapted
Businesses do not stand still. Processes change, new rules appear, and new stores, regions and systems arrive. An integration that is hard to change soon becomes something everyone works around, so we build them to be adapted over time.
Keep each flow focused on one job, keep the business rules explicit and easy to find rather than buried in the plumbing, and keep them documented. Then changing a rule is a small, safe edit, not a rewrite.
On the retail platform, each pipeline moves one kind of record in one direction, so a change to one process does not disturb the rest. The same design let us support the move of inventory to a new system without tearing the platform up.
Which end are you at?
A few questions help place you.
- How many systems and regions are involved? Two systems in one place is a tactical integration. Several systems across regions and currencies is closer to an enterprise platform.
- What happens if it silently goes wrong? The more that depends on the numbers being right, the more audit, reconciliation and alerting you need.
- Who needs to understand it? If one person can own it, keep it simple. If a team will run it for years, document it and test it.
- How fast is the business changing? New stores, new regions and new systems favour focused, independent flows.
You do not have to start at the enterprise end. Most good integrations begin small and grow into what they need, which is why the principles matter more than the tooling. Pick the lightest tool that can do the job properly, and be willing to move up when it cannot.
If you are weighing up where to start, our Data & Application Integration service is built around exactly these steps, and we are happy to talk it through.